 GITHUB.COM
TOOLSMONTH NOVEMBER
AlohaMini
GitHub - liyiteng/AlohaMini: Open-Source Dual-Arm Mobile Robot with Motorized Lift
Open-Source Dual-Arm Mobile Robot with Motorized Lift - liyiteng/AlohaMini
AN IN-DEPTH REPOSITORY
Every model, paper, media release, agent and tool from the month—in one source-linked archive.
COMPLETE MONTHLY ARCHIVE
World models, computer-use agents and a new generation of image and video systems pushed AI from standalone models toward interactive creative infrastructure.
THE COMPLETE MONTHLY INDEX
Every linked paper, product release, research project and article has been checked directly. Cards use the publication's own description, imagery and published date wherever the source supplied them.
The AI Search helps discover the wider field, while every available card opens the original publication. Dates come only from publication metadata or official source APIs—never from a video. A checked date records our review, not the release. Older undated entries show their archive month.
GITHUB.COMGitHub - liyiteng/AlohaMini: Open-Source Dual-Arm Mobile Robot with Motorized Lift
Open-Source Dual-Arm Mobile Robot with Motorized Lift - liyiteng/AlohaMini
Chatgpt Shopping Research is linked to its original publication. Open the source for the author’s release notes, demonstrations and technical details.
 ANTHROPIC.COM
Introducing Claude Opus 4.5
Anthropic is an AI safety and research company that's working to build reliable, interpretable, and steerable AI systems.
 HUGGINGFACE.CO
deepseek-ai/DeepSeek-Math-V2 · Hugging Face
DeepSeek Math V2 is published at its original model or project page. Open the source for documentation, files, demonstrations and usage details.
 MICROSOFT.COM
Fara-7B: An efficient agentic small language model for computer use
Fara-7B is our first agentic small language model for computer use. This experimental model includes robust safety measures to aid responsible deployment. Despite its size, Fara-7B holds its own against larger, more resource-intensive agentic systems:
 BFL.AI
FLUX.2: Frontier Visual Intelligence
Today, we release FLUX.2, our most capable model to date.
 EKONWANG.GITHUB.IO
GeoVista
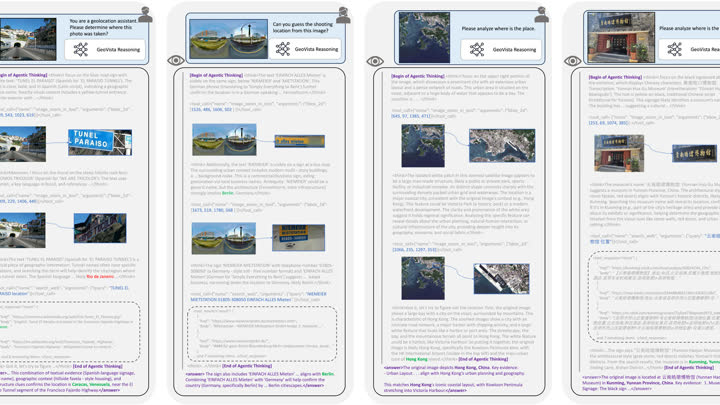
GeoVista: Web-Augmented Agentic Visual Reasoning for Geolocalization
iMontage
IMontage Web is linked to its original publication. Open the source for the author’s release notes, demonstrations and technical details.
 GITHUB.COM
GitHub - alibaba-damo-academy/RynnVLA-002: RynnVLA-002: A Unified Vision-Language-Action and World Model
RynnVLA-002: A Unified Vision-Language-Action and World Model - alibaba-damo-academy/RynnVLA-002
Tencent Hy is linked to its original publication. Open the source for the author’s release notes, demonstrations and technical details.
 GITHUB.COM
GitHub - Tongyi-MAI/Z-Image
Contribute to Tongyi-MAI/Z-Image development by creating an account on GitHub.
 ANTIGRAVITY.GOOGLE
Google Antigravity
Experience liftoff with the next-gen agent platform
Depth Anything 3: Recovering the Visual Space from Any Views
Depth Anything 3 is linked to its original publication. Open the source for the author’s release notes, demonstrations and technical details.
 GITHUB.COM
GitHub - rlresearch/dr-tulu: Official repository for DR Tulu: Reinforcement Learning with Evolving Rubrics for Deep Research
Official repository for DR Tulu: Reinforcement Learning with Evolving Rubrics for Deep Research - rlresearch/dr-tulu
Gpt 5 1 Codex Max is linked to its original publication. Open the source for the author’s release notes, demonstrations and technical details.
 X.AI
Grok 4 1 is linked to its original publication. Open the source for the author’s release notes, demonstrations and technical details.
 GITHUB.COM
GitHub - Tencent-Hunyuan/HunyuanVideo-1.5: HunyuanVideo-1.5: A leading lightweight video generation model
HunyuanVideo-1.5: A leading lightweight video generation model - Tencent-Hunyuan/HunyuanVideo-1.5
 KANDINSKYLAB.AI
Kandinsky Lab — Generative AI Research
Open state-of-the-art image and video generation models. Open research, open code.
PART-X-MLLM: Part-Aware 3D Multimodal Large Language Model
Part-X-MLLM is a part-aware 3D multimodal large language model for unified 3D generation, editing, and grounding via programmatic part-level reasoning.
PhysX-Anything: Simulation-Ready Physical 3D Assets from Single Image
PhysX-Anything: Simulation-Ready Physical 3D Assets from Single Image
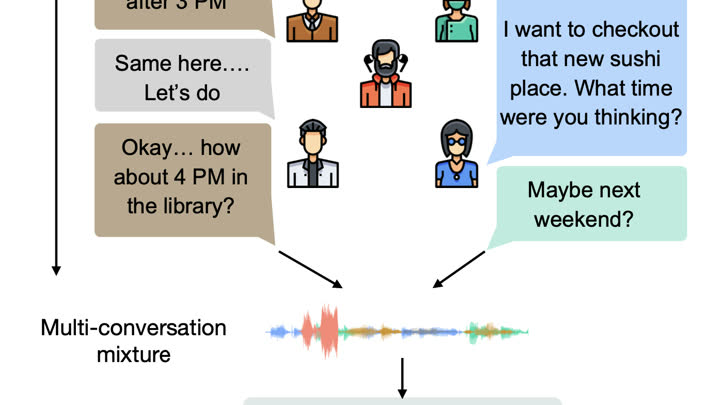 PROACTIVEHEARING.CS.WASHINGTON.EDU
Proactive Hearing Assistants that Isolate Egocentric Conversations
Proactivehearing is linked to its original publication. Open the source for the author’s release notes, demonstrations and technical details.
Sam 3d is linked to its original publication. Open the source for the author’s release notes, demonstrations and technical details.
Segment Anything Model 3 is linked to its original publication. Open the source for the author’s release notes, demonstrations and technical details.
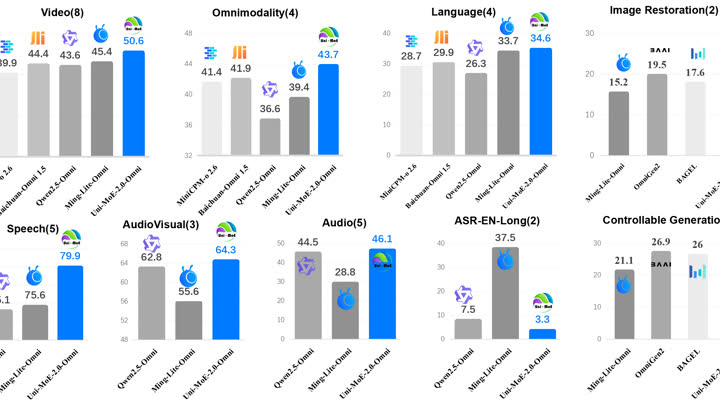 IDEALISTXY.GITHUB.IO
Uni-MoE-2.0-Omni
Scaling Unified Multimodal LLMs with Mixture of Experts