CREATECH NORTH: AI LEAP

AN IN-DEPTH REPOSITORY

THE MONTHLY
SIGNAL

Every model, paper, media release, agent and tool from the month—in one source-linked archive.

956 SIGNALS12 ISSUESSOURCE-LINKED

COMPLETE MONTHLY ARCHIVE

July 2026

The frontier shipped: faster model families, natural voice, embodied navigation and the infrastructure needed to put agents into real work.

THE COMPLETE MONTHLY INDEX

Every Signal

92ITEMS IN JULY 2026 / COMPLETE

Every linked paper, product release, research project and article has been checked directly. Cards use the publication's own description, imagery and published date wherever the source supplied them.

The AI Search helps discover the wider field, while every available card opens the original publication. Dates come only from publication metadata or official source APIs—never from a video. A checked date records our review, not the release. Older undated entries show their archive month.

92 results
Publication preview for DeepSeek V4 Flash 0731HUGGINGFACE.CO
MODELSPUBLISHED 31 July

DeepSeek V4 Flash 0731

DeepSeek-V4-Flash-0731

DeepSeek’s official V4 Flash release substantially improves agentic performance over the preview while retaining its speculative-decoding module and supporting low, high and max reasoning effort.
Publication preview for MiniMax H3MINIMAX.IO
MODELSPUBLISHED 31 July

MiniMax H3

MiniMax H3: An Open Model Breaking the Boundaries Between Tasks and Modalities - MiniMax Research

Today, we're officially launching MiniMax H3, a general-purpose omni-modal generation model. H3 can jointly understand multimodal contexts spanning text, images, video, and audio. It generates video with native stereo audio at up to 2K resolution and 15…

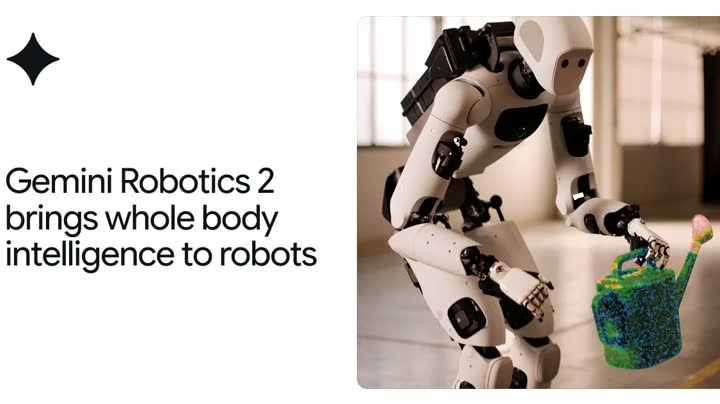
Publication preview for Gemini Robotics 2DEEPMIND.GOOGLE
RESEARCHPUBLISHED 30 July

Gemini Robotics 2

Gemini Robotics 2 brings whole body intelligence to robots

From feet to fingertips — we are teaching robots intelligent whole-body control, fine dexterity, and teamwork to complete a broad range of complex tasks.

Publication preview for GPT-5.6 price-performance updateOPENAI.COM
MODELSPUBLISHED 30 July

GPT-5.6 price-performance update

Advancing the price-performance frontier with GPT-5.6

OpenAI cut GPT-5.6 Luna pricing by 80% and Terra pricing by 20%, while introducing a Fast API mode for higher-throughput GPT-5.6 Sol workloads.

Publication preview for Multi-Agent CADGITHUB.COM
AGENTSPUBLISHED 30 July

Multi-Agent CAD

GitHub - Pan-Chera/Multi-Agent-CAD: MAC (Multi-Agent CAD): A decoupled multi-agent framework for text-to-CAD generation via constrained test-time compute

MAC (Multi-Agent CAD): A decoupled multi-agent framework for text-to-CAD generation via constrained test-time compute - Pan-Chera/Multi-Agent-CAD

Publication preview for Science One FrameworkRESEARCH.GOOGLE
AGENTSPUBLISHED 30 July

Science One Framework

Science One Framework: A verifiable autonomous research framework via Chain-of-Evidence

Google Research introduced an autonomous research prototype that builds an auditable chain of evidence as it works, paired with CoE Audit for checking the integrity of AI-generated papers.

Publication preview for Gemini natural voice typingBLOG.GOOGLE
TOOLSPUBLISHED 29 July

Gemini natural voice typing

Gemini for macOS adds new natural language capabilities

A look at how the Gemini app for macOS now lets you speak naturally to get clean transcriptions, edits, and summaries just using your voice.

MediaORIGINAL SOURCEDEEPMIND.GOOGLE
MEDIAPUBLISHED 29 July

Lyria 3.5

Lyria 3.5 — Model Card

Google's latest music-generation model improves musicality, vocals, lyrics, audio fidelity and prompt control while producing cohesive tracks as long as three minutes in Flow Music.

Publication preview for Qwen-Audio 3.0 Gen PreviewARXIV.ORG
MEDIAPUBLISHED 29 July

Qwen-Audio 3.0 Gen Preview

Qwen-Audio-3.0-Gen-Preview Technical Report

Qwen’s technical report presents a unified audio-generation model spanning speech, music and general sound, with controllable generation and a shared multimodal architecture.

ResearchORIGINAL SOURCEDEEPMIND.GOOGLE
RESEARCHPUBLISHED 28 July

Visual Prompt Engineering

Visual prompt engineering for video models

Google DeepMind found that automatically editing a task image before inference can improve video-model reasoning more than text-only prompt engineering or extra test-time compute.

Publication preview for Cosmos-H-DreamsHUGGINGFACE.CO
MODELSPUBLISHED 27 July

Cosmos-H-Dreams

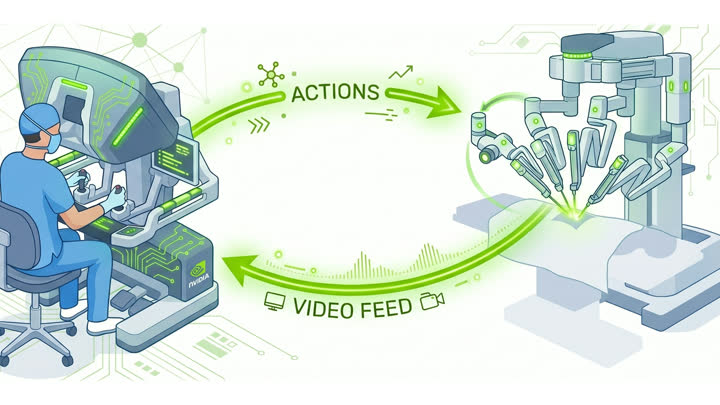
NVIDIA Cosmos-H-Dreams: Bringing Real-Time Generative Simulation to Surgical Robotics

NVIDIA released a real-time, action-conditioned surgical world model that lets operators and learned robot policies act inside generated surgical scenes and observe the results interactively.

Publication preview for Inkling SmallHUGGINGFACE.CO
MODELSPUBLISHED 27 July

Inkling Small

Thinking Machines released a 276B-total, 12B-active open multimodal model that accepts text, images and audio for coding, tool use, conversational and retrieval workflows.

Publication preview for Claude Opus 5ANTHROPIC.COM
MODELSMONTH JULY

Claude Opus 5

Introducing Claude Opus 5

Opus 5 is a step change improvement for the Opus tier powering long-running agents while delivering improvements in coding and professional work.

Publication preview for FLUX 3BFL.AI
MEDIAMONTH JULY

FLUX 3

FLUX 3: One Multi-Modal Model | Black Forest Labs

One multi-modal model for Image, Video, Audio and Action-Prediction. Creations are truer to life in every kind of style.

Publication preview for GLM 5.2 Vision NVFP4HUGGINGFACE.CO
MODELSMONTH JULY

GLM 5.2 Vision NVFP4

baseten/GLM-5.2-Vision-NVFP4 · Hugging Face

GLM 5.2 Vision NVFP4 is published on Hugging Face. Open the model or project card for the author’s documentation, files, license and usage details.

Publication preview for Health in ChatGPTOPENAI.COM
TOOLSMONTH JULY

Health in ChatGPT

Health in ChatGPT links to its original tools page, but the publisher did not expose a readable preview. Open the source directly for the full release.

Publication preview for Laguna S 2.1POOLSIDE.AI
MODELSMONTH JULY

Laguna S 2.1

Introducing Laguna S 2.1

Today we’re releasing Laguna S 2.1, a significant step forward in our development of models that pursue longer horizon work and make effective use of reasoning.

Publication preview for Mage-FlowHUGGINGFACE.CO
MEDIAMONTH JULY

Mage-Flow

microsoft/Mage-Flow · Hugging Face

Mage-Flow is published on Hugging Face. Open the model or project card for the author’s documentation, files, license and usage details.

Publication preview for Nanbeige 4.2 3BMODELSCOPE.AI
MODELSMONTH JULY

Nanbeige 4.2 3B

Nanbeige4.2-3B

ModelScope——A one-stop service that brings together the most advanced machine learning models from various fields, offering model exploration experience, inference, training, deployment, and application.

Publication preview for OpenAI–Hugging Face security incidentOPENAI.COM
RESEARCHMONTH JULY

OpenAI–Hugging Face security incident

OpenAI–Hugging Face security incident links to its original research page, but the publisher did not expose a readable preview. Open the source directly for the full release.

Publication preview for OpenDreamerNEXT-STATE.GITHUB.IO
RESEARCHMONTH JULY

OpenDreamer

How to train a frontier-level world model

How we trained and open-sourced a frontier-level world model — the lessons, failures, and fixes — with a live, playable demo running on Reactor.

QWEN.AI
MEDIAMONTH JULY

Qwen-Image 3.0

Qwen Studio

Qwen Studio offers comprehensive functionality spanning chatbot, image and video understanding, image generation, document processing, web search integration, tool utilization, and artifacts.